
· By HeyData team
Starting a Qlik project: exploring and extracting the data
Welcome to the very first article on the blog!
To launch it, we are drawing the same parallel as with the start of any successful Qlik project: we begin by laying the foundations. Our aim is to share our vision with you and to consolidate our experience in content that is accessible, rigorous and useful.
On this blog, we will cover topics that are both highly technical (scripting, modelling, performance) and broader (modern BI and the Qlik ecosystem).
Why Qlik? The fundamentals
The data from your business (finance, HR, orders, etc.) is often stored in one or more databases managed by dedicated software. While these tools are excellent for operations, they rarely offer advanced analysis and statistics features.
One of Qlik’s key uses is to make this data available beyond the users of the management software, while providing superior analysis capabilities.
To achieve this, the main phases of a project are always the same:
- Connect to the source and extract the data.
- Transform it into an optimised data model.
- Create indicators and a relevant design.
As you will have gathered, the first step is to master the source. We will focus on the critical phases that are often overlooked:
- Understanding the structure of the data source.
- Exploring its actual content to prepare the modelling.
These steps are essential for any high-performing analytical model; find out how to master them.
Phase 1 – Understanding the structure and logic of the database
Most Qlik projects rely on one or more databases from business software: financial management, HR, production or logistics. These systems store data in a relational model, optimised for operations but rarely designed for analysis.
For the developer, this first phase is a “miner’s” job: documentation is often incomplete and the relationships between tables are far from explicit. It is often tedious and highly technical.
To avoid moving forward blindly, mapping the database is essential. We will share tools and tips to speed up and industrialise this crucial step of identifying:
- the relevant schemas and tables;
- the implicit relationships and functional keys;
- the fields that carry business value.
Mastering this mapping is the key to simplifying the rest of the project and the preparation of your Qlik data model.
Accessing the schema
The first step is to retrieve the complete schema of the database to get a detailed view of its structure. Let’s take the example of a PostgreSQL database, although the equivalent can be done for other technologies.
A simple script lists all tables and columns automatically. You just need to connect by entering the connection string, then run the following script:
// Initialiser la Data Connexion
LIB CONNECT TO 'PG-northwind';

// Filtrer le schéma qui nous intéresse
SET vSchema = 'public';

// Chargement des colonnes
Columns:
LOAD
    table_name,
    column_name,
    data_type;

SELECT
    "table_name",
    "column_name",
    "data_type"
FROM "information_schema"."columns"
WHERE table_schema = '$(vSchema)';

// Chargement des tables
Tables:
LOAD
    table_name,
    table_type;

SELECT
    "table_name",
    "table_type"
FROM "information_schema"."tables"
WHERE table_schema = '$(vSchema)';
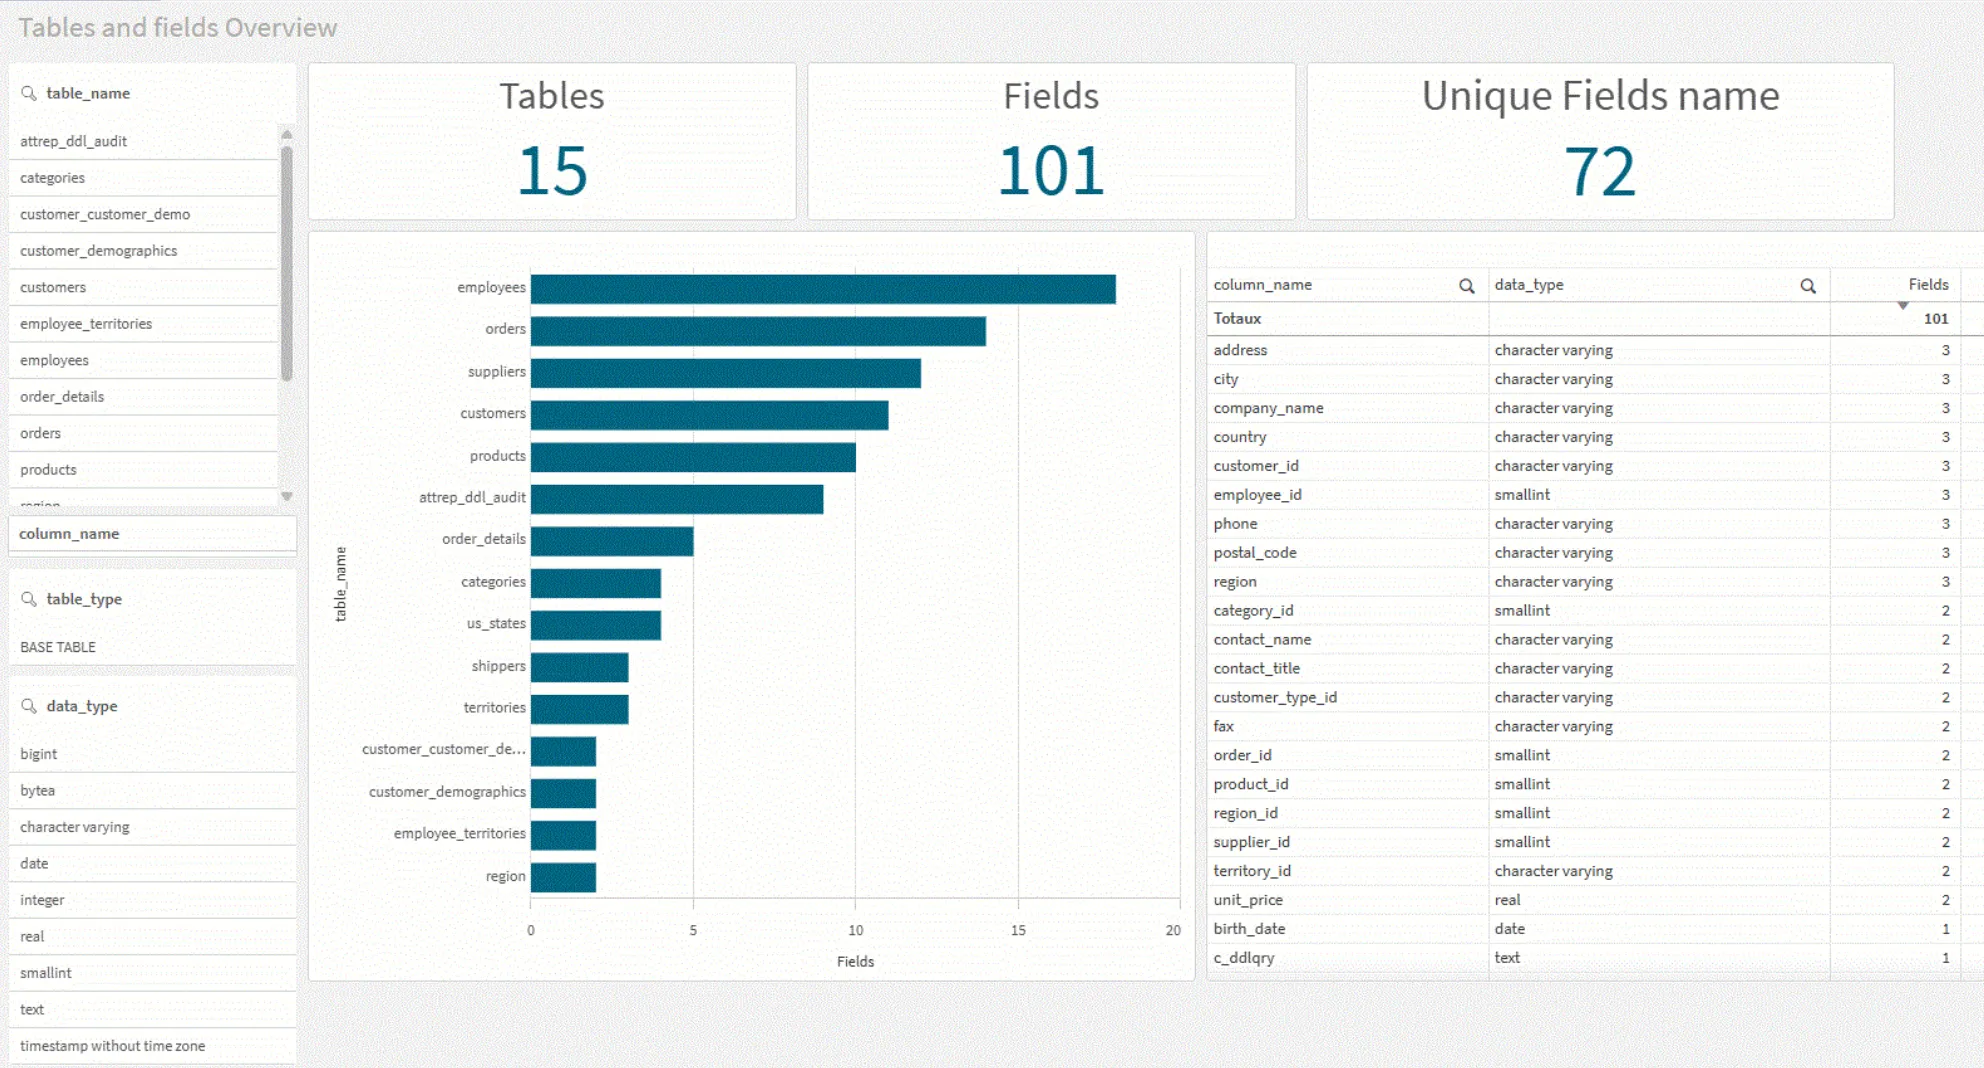
With this extraction, you can quickly build a structural exploration dashboard showing:
- the list of tables;
- the field types;
- the presence of keys.
Why is this mapping essential?
This initial analysis makes it possible to:
- assess the quality of the relational model;
- anticipate the transformations needed for an analytical model;
- spot unnecessary technical fields;
- understand the granularity of the data;
- detect fact tables, dimension tables or mixed tables;
- identify the keys and relationships between tables.
This is the stage where you start to picture the final structure of the Qlik model, bearing in mind that the original model will never be used as is.
Transformations, merges and enrichments will always be necessary.
Phase 2 – Exploring the actual content to prepare the modelling
Once the structure of the database has been mapped, the next step is to extract the data so that it can be viewed in Qlik. This phase must be optimised for speed, as it will be repeated until we have identified all the relevant data.
Extraction strategy by data volume
How we extract the data depends heavily on the volume of the source tables:
- Reasonable volume: we perform a full load of all data rows.
- Large volume: for very large tables, we prefer a partial load.
The extraction script and the role of the QVD
Our approach is to run a “SELECT *” on all the relevant tables of the data model and store them immediately in QVD files.
This initial load is done with a fairly simple script, shown here:
FOR EACH vTable IN FieldValueList('table_name')

    tmp:
    SELECT
        COUNT(*) AS no_rows
    FROM "$(vSchema)"."$(vTable)";

    LET vNoRows = Peek('no_rows');
    TRACE lignes : $(vNoRows);

    DROP TABLE tmp;

    IF vNoRows > 500 THEN

        $(vTable):
        FIRST 100
        SELECT *
        FROM "$(vSchema)"."$(vTable)";

    ELSE

        $(vTable):
        SELECT *
        FROM "$(vSchema)"."$(vTable)";

    ENDIF;

    STORE $(vTable)
        INTO Lib://$(vDataConnexion)/$(vDatabaseQvds)/$(vTable).qvd (qvd);

    DROP TABLE $(vTable);

NEXT;
This method has two major advantages:
- Speed: QVD is a format optimised for Qlik, making future reloads almost instantaneous.
- Separation: QVDs act as a raw storage layer, isolated from the transformation logic.
Preparing for viewing: the “Qualify” tip
The “Qualify” tip prefixes every field with the name of its source table. The goal is simple: to prevent links between tables from being created automatically in the Qlik data model. For this exploration phase, we just want to view the tables in isolation, without any analytical structure.
QUALIFY *;

LOAD
    *
FROM [lib://$(vDataConnexion)/$(vDatabaseQvds)/*.qvd]
(qvd);
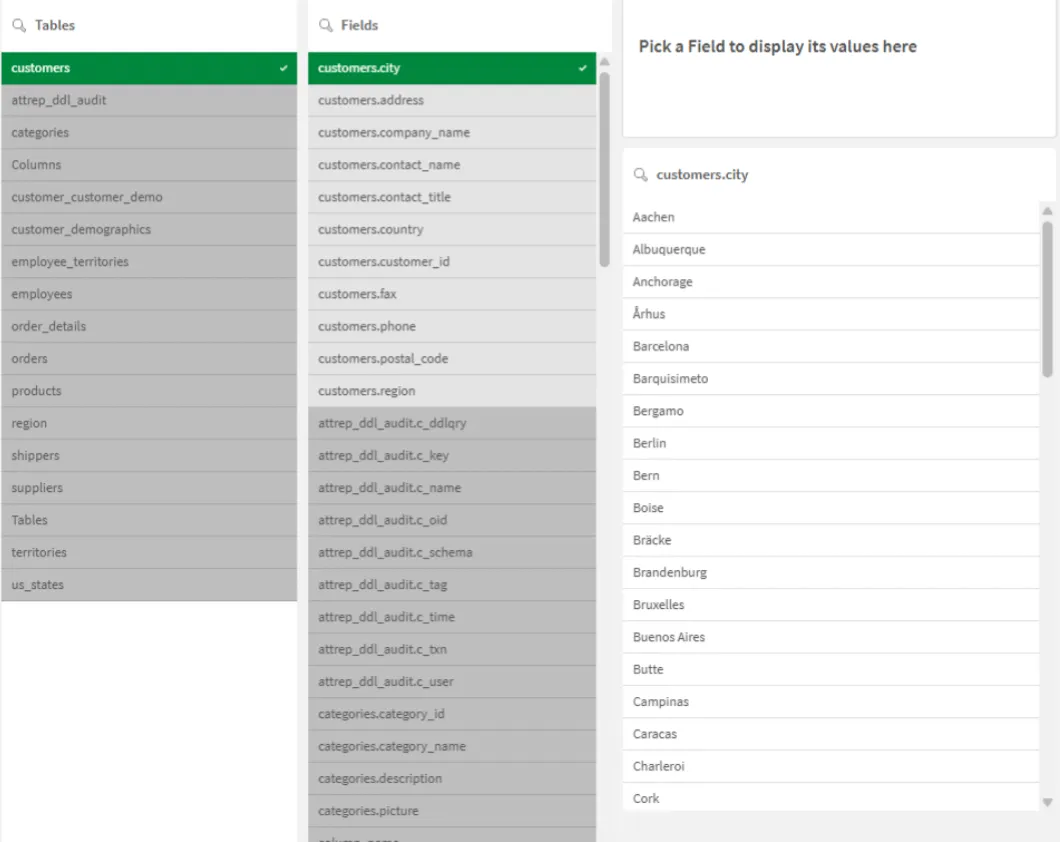
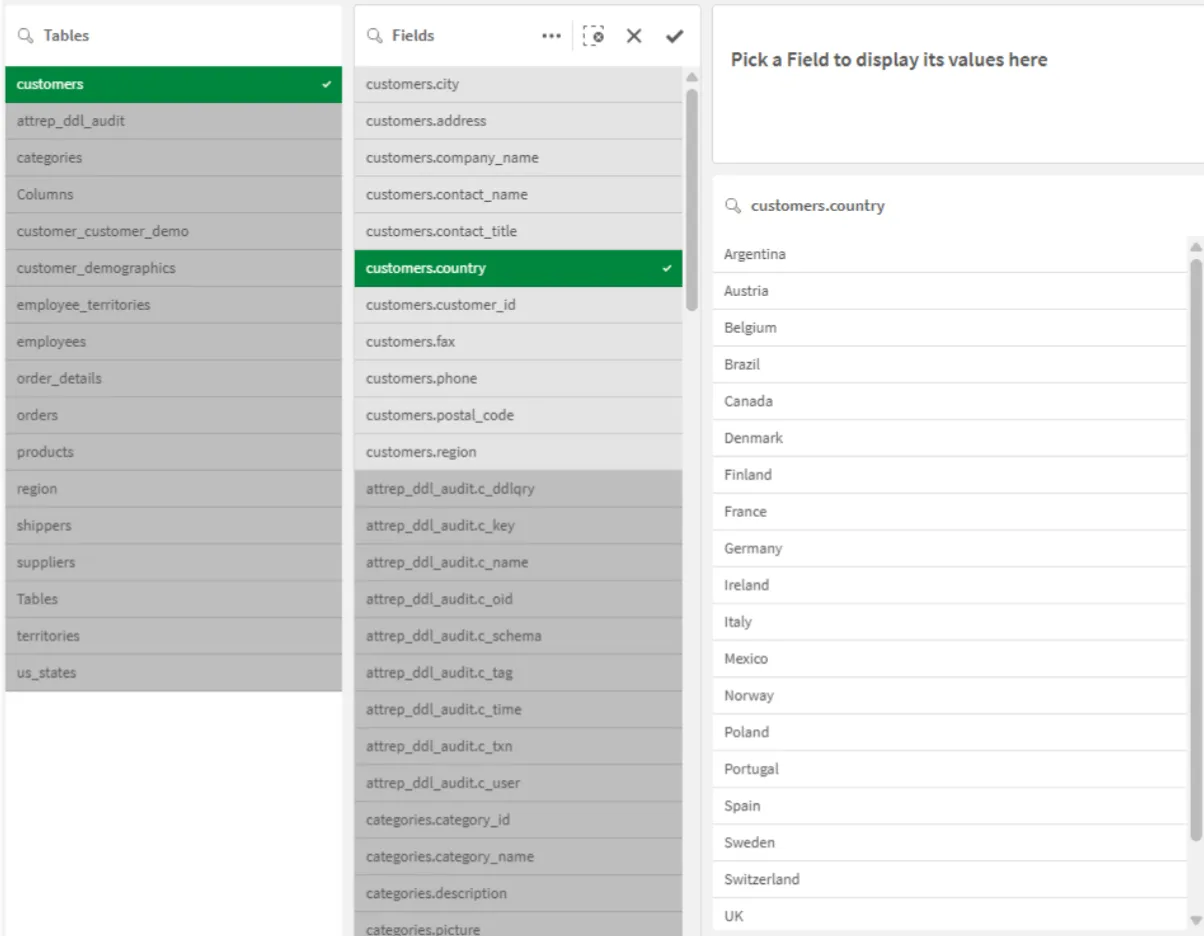
Exploring with smart search
Once the data is loaded, the Qlik application (in a sheet dedicated to exploration) becomes a powerful search tool. If you are looking for a specific value without knowing which field it is stored in, Qlik’s smart search is your best ally. It lets you find data and trace it back to its source, even within a model you have not yet mastered.
Optimising for exploration
To keep this phase fast, remember to add this variable to your script:
SET CreateSearchindexOnReload=0This stops Qlik from indexing the content of every field during the load, which speeds up reload times while you work on the extraction. (Also note that the QVD storage path will be managed by project variables, to be adapted to your file system.)
This exploration method applies to any Qlik project based on a database. Because it is quick to implement, it is a useful aid to technical and functional decision-making.
This exploration environment is indeed ideal for discussions with business experts (developers, users, database administrators) to validate the relevance of the data and establish the business rules needed for the indicators.
Here is the sample application to use: Heydata_1 – GoaGS – 1.qvf
Once the source data is mastered and its future use defined, we can move on to the industrialisation of the extraction, which will be the subject of our next article.
See you soon!